What kind of websites can you scrape?
Public pages that the site's terms and the law allow. Feasibility depends on the site, so I check it before committing to anything.
Home / Services / Web Scraping & Data Extraction
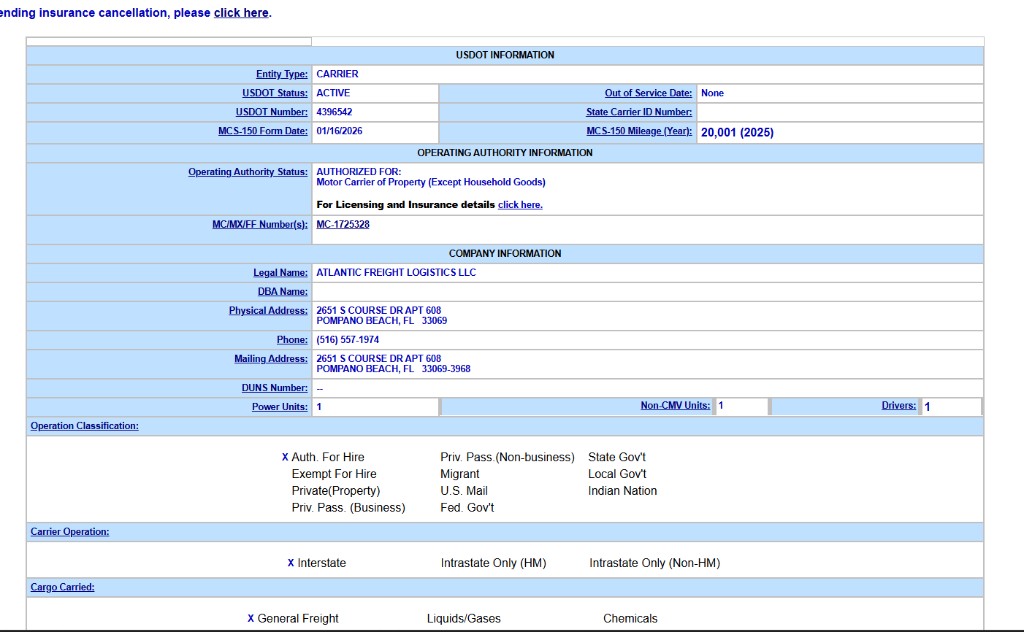
I build scrapers and extraction tools that turn public web pages into clean spreadsheets or databases. Examples below include lead research, US carrier (FMCSA/SAFER) data and full-site extraction, all with public source.
Copying data from websites into spreadsheets by hand
Carrier or lead lists that go stale because nobody re-checks them
One-off scripts that break and nobody can re-run
Data scattered across PDFs and web pages
Lead-research CRM: Playwright scraping, BullMQ/Redis job queue, MongoDB storage, Excel export, Next.js dashboard and Electron desktop build.
Python Selenium scraper for carrier and MC data from FMCSA SAFER.
Searchable US trucking carrier directory built on public FMCSA data. Write-up: https://dev.to/mafzalkalwardev/indus-carrier-directory-looking-up-freight-carriers-with-fmcsa-data-bk2
Website scraping and cloning toolkit using Playwright.
I don't publish client names, call volumes or results I can't show. The repositories and Chrome Web Store listings are the public record.
Public pages that the site's terms and the law allow. Feasibility depends on the site, so I check it before committing to anything.
Yes, I have public projects for it (fmcsa-safer-scraper, safer-carrier-extractor, indus-carrier-directory). Where FMCSA offers official datasets or APIs, those are usually the better source.
My existing tools export CSV and Excel and store data in MongoDB. Other formats can be agreed during scoping.
Sites do change. Whether ongoing maintenance is included is part of the scope we would agree in writing.
Pricing depends on scope - contact me with what you need and I'll reply with questions before any estimate.